/ Exploring
Updated
Consulting AI Benchmark
Three AI tools compared on 23 consulting test cases.
Demo
See it in action
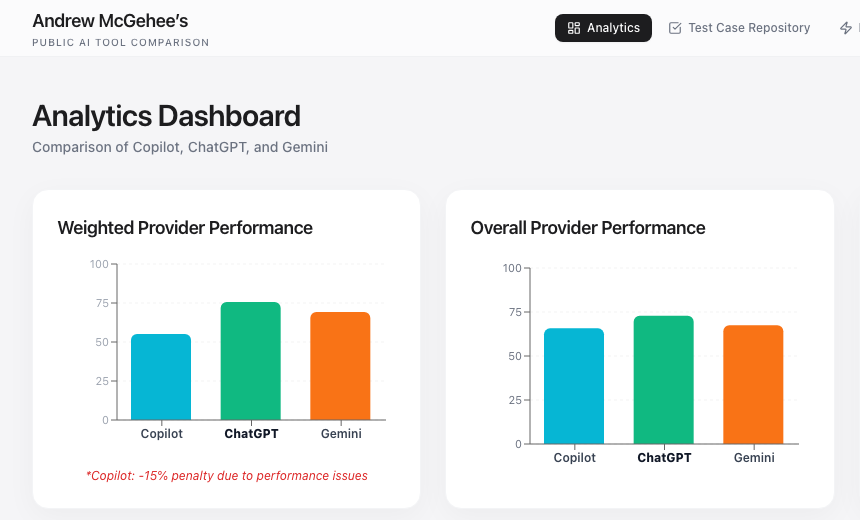
This comparison used 23 consulting cases with AI-generated logistics data. Five to ten colleagues used the dashboard during the November–December 2025 evaluation. Its conclusions belong to those tasks and that period; they do not establish a current ranking for every consulting workflow.
Why I built it
I wanted to compare AI tools on consulting tasks. I used AI-generated logistics cases so the evaluation would contain no proprietary client information.
What I built
Five to ten colleagues used the dashboard during the evaluation.
I built it in November and December 2025. The dashboard compared Copilot, ChatGPT, and Gemini. It helped identify OpenAI as the front-runner for our use cases. As part of the same evaluation, Anthropic was ruled out because its token-based costs were too unpredictable and high.
What I learned
Building the dashboard was easier than designing the benchmark. Easy test cases made every model look good and did not help with the decision.
The comparison needed to show task quality and cost predictability, not just one overall score.
What I’d change
I would automate the tests with Promptfoo and make the cases harder.
I would also show where the test data is too thin to support a firm conclusion.
How I built it
I built the dashboard on Google Cloud Run, with Firestore for results and the Google GenAI SDK for inference. It groups results by provider and task type, with weighted and overall scores.
The PowerPoint Benchmark now provides inspectable slide evidence and a separate methodology resource.