- OpenAI
- Anthropic
- Other
- Frontier
No plotted models match this filter.
By Andrew McGehee · Compact results · Methodology and prompt · Results JSON
I built a repeatable benchmark to find out which AI can produce a usable, editable corporate deck.
66 AI model and reasoning configurations from OpenAI, Anthropic and other labs each built the same editable consulting deck on one corporate PowerPoint master and slide library. Claude Opus 5.5 · XHigh currently ranks first.
01 — Results
An AI judge panel compares decks two at a time. A win score of 50 means even odds against a typical model. The panel agreed with human reviewers on 92% of 49 test pairs.
Up and to the left is better.
No plotted models match this filter.
02 — Models
One row per model, ranked by its best tested win score. Cost and time use that same effort setting. Expand a model for every tested effort level.
| Rank | Provider | Model | Best effort | Compare | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| 01 | Anthropic | Claude Opus 5.5 | Xhigh | 97.9 | 22m 22s | $6.54 | Compare decks | |||
| Config.61 | Anthropic | Claude Opus 5.5 | Low | 6.7Elo 1,043 · 3 decks, 95% interval 2.2–11.8 | 1m 27s | $0.49API estimate | Compare decks | Details for Claude Opus 5.5, LowElo 1,043 · 3 decks 95% interval: 2.2–11.8 Time: Mean · n=3 Cost: API-equivalent estimate · n=3 Release: Sep 22, 2026 | ||
| Config.14 | Anthropic | Claude Opus 5.5 | Medium | 80.1Elo 1,742 · 4 decks, 95% interval 66.7–90.3 | 7m 58s | $1.73API estimate | Compare decks | Details for Claude Opus 5.5, MediumElo 1,742 · 4 decks 95% interval: 66.7–90.3 Time: Mean · n=4 Cost: API-equivalent estimate · n=4 Release: Sep 22, 2026 | ||
| Config.07 | Anthropic | Claude Opus 5.5 | High | 93.6Elo 1,967 · 6 decks, 95% interval 89.8–97.1 | 10m 32s | $2.87API estimate | Compare decks | Details for Claude Opus 5.5, HighElo 1,967 · 6 decks 95% interval: 89.8–97.1 Time: Mean · n=6 Cost: API-equivalent estimate · n=6 Release: Sep 22, 2026 | ||
| Config.01 | Anthropic | Claude Opus 5.5 | Xhigh | 97.9Elo 2,168 · 7 decks, 95% interval 95.7–99.5 | 22m 22s | $6.54API estimate | Compare decks | Details for Claude Opus 5.5, XhighElo 2,168 · 7 decks 95% interval: 95.7–99.5 Time: Mean · n=7 Cost: API-equivalent estimate · n=7 Release: Sep 22, 2026 | ||
| Config.02 | Anthropic | Claude Opus 5.5 | Max | 97.4Elo 2,130 · 7 decks, 95% interval 95.6–99 | 40m 00s | $12.86API estimate | Compare decks | Details for Claude Opus 5.5, MaxElo 2,130 · 7 decks 95% interval: 95.6–99 Time: Mean · n=7 Cost: API-equivalent estimate · n=7 Release: Sep 22, 2026 | ||
| 02 | Anthropic | Claude Sonnet 5.5 | Max | 96.9 | 72m 56s | $21.39 | Compare decks | |||
| Config.32 | Anthropic | Claude Sonnet 5.5 | Medium | 59.2Elo 1,564 · 3 decks, 95% interval 40.1–76.4 | 3m 17s | $0.94Reported | Compare decks | Details for Claude Sonnet 5.5, MediumElo 1,564 · 3 decks 95% interval: 40.1–76.4 Time: Mean · n=3 Cost: Provider-reported · n=3 Release: Sep 28, 2026 | ||
| Config.16 | Anthropic | Claude Sonnet 5.5 | High | 79.8Elo 1,739 · 3 decks, 95% interval 67–91.7 | 6m 36s | $1.96Reported | Compare decks | Details for Claude Sonnet 5.5, HighElo 1,739 · 3 decks 95% interval: 67–91.7 Time: Mean · n=4 Cost: Provider-reported · n=4 Release: Sep 28, 2026 | ||
| Config.10 | Anthropic | Claude Sonnet 5.5 | Xhigh | 90.6Elo 1,893 · 4 decks, 95% interval 83.5–95.5 | 25m 18s | $7.04Reported | Compare decks | Details for Claude Sonnet 5.5, XhighElo 1,893 · 4 decks 95% interval: 83.5–95.5 Time: Mean · n=4 Cost: Provider-reported · n=4 Release: Sep 28, 2026 | ||
| Config.03 | Anthropic | Claude Sonnet 5.5 | Max | 96.9Elo 2,099 · 5 decks, 95% interval 94.5–98.9 | 72m 56s | $21.39Reported | Compare decks | Details for Claude Sonnet 5.5, MaxElo 2,099 · 5 decks 95% interval: 94.5–98.9 Time: Mean · n=5 Cost: Provider-reported · n=5 Release: Sep 28, 2026 | ||
| 03 | OpenAI | GPT-6 Astra | Xhigh | 94.3 | 11m 16s | $3.31 | Compare decks | |||
| Config.30 | OpenAI | GPT-6 Astra | Low | 59.7Elo 1,568 · 5 decks, 95% interval 43.3–75.1 | 4m 34s | $1.47API estimate | Compare decks | Details for GPT-6 Astra, LowElo 1,568 · 5 decks 95% interval: 43.3–75.1 Time: Mean · n=5 Cost: API-equivalent estimate · n=5 Release: Sep 3, 2026 | ||
| Config.38 | OpenAI | GPT-6 Astra | Medium | 52.1Elo 1,515 · 4 decks, 95% interval 37.9–66 | 4m 33s | $1.35API estimate | Compare decks | Details for GPT-6 Astra, MediumElo 1,515 · 4 decks 95% interval: 37.9–66 Time: Mean · n=4 Cost: API-equivalent estimate · n=4 Release: Sep 3, 2026 | ||
| Config.18 | OpenAI | GPT-6 Astra | High | 78.6Elo 1,726 · 5 decks, 95% interval 65.7–88 | 6m 33s | $2.36API estimate | Compare decks | Details for GPT-6 Astra, HighElo 1,726 · 5 decks 95% interval: 65.7–88 Time: Mean · n=5 Cost: API-equivalent estimate · n=5 Release: Sep 3, 2026 | ||
| Config.04 | OpenAI | GPT-6 Astra | Xhigh | 94.3Elo 1,989 · 8 decks, 95% interval 91.2–97.6 | 11m 16s | $3.31API estimate | Compare decks | Details for GPT-6 Astra, XhighElo 1,989 · 8 decks 95% interval: 91.2–97.6 Time: Mean · n=9 Cost: API-equivalent estimate · n=9 Release: Sep 3, 2026 | ||
| Config.09 | OpenAI | GPT-6 Astra | Max | 92.0Elo 1,924 · 6 decks, 95% interval 86.8–96.9 | 17m 21s | $4.49API estimate | Compare decks | Details for GPT-6 Astra, MaxElo 1,924 · 6 decks 95% interval: 86.8–96.9 Time: Mean · n=6 Cost: API-equivalent estimate · n=6 Release: Sep 3, 2026 | ||
| Config.05 | OpenAI | GPT-6 Astra | Ultra | 94.2Elo 1,985 · 1 deck, 95% interval 78.7–98.8 | 8m 10s | $2.58API estimate | Compare decks | Details for GPT-6 Astra, UltraElo 1,985 · 1 deck 95% interval: 78.7–98.8 Time: Mean · n=1 Cost: API-equivalent estimate · n=1 Release: Sep 3, 2026 | ||
| 04 | OpenAI | GPT-5.6 Sol | Max | 94.0 | 17m 45s | $3.05 | Compare decks | |||
| Config.37 | OpenAI | GPT-5.6 Sol | High | 52.9Elo 1,520 · 5 decks, 95% interval 34.7–66.5 | 21m 32s | $1.55API estimate | Compare decks | Details for GPT-5.6 Sol, HighElo 1,520 · 5 decks 95% interval: 34.7–66.5 Time: Mean · n=5 Cost: API-equivalent estimate · n=5 Release: Jul 9, 2026 | ||
| Config.24 | OpenAI | GPT-5.6 Sol | Xhigh | 73.2Elo 1,675 · 4 decks, 95% interval 58.7–84.3 | 23m 59s | $2.36API estimate | Compare decks | Details for GPT-5.6 Sol, XhighElo 1,675 · 4 decks 95% interval: 58.7–84.3 Time: Mean · n=4 Cost: API-equivalent estimate · n=4 Release: Jul 9, 2026 | ||
| Config.06 | OpenAI | GPT-5.6 Sol | Max | 94.0Elo 1,978 · 8 decks, 95% interval 88.6–97.8 | 17m 45s | $3.05API estimate | Compare decks | Details for GPT-5.6 Sol, MaxElo 1,978 · 8 decks 95% interval: 88.6–97.8 Time: Mean · n=8 Cost: API-equivalent estimate · n=8 Release: Jul 9, 2026 | ||
| Config.08 | OpenAI | GPT-5.6 Sol | Ultra | 93.3Elo 1,959 · 1 deck, 95% interval 68.4–99.3 | 15m 52s | $3.38API estimate | Compare decks | Details for GPT-5.6 Sol, UltraElo 1,959 · 1 deck 95% interval: 68.4–99.3 Time: Mean · n=1 Cost: API-equivalent estimate · n=1 Release: Jul 9, 2026 | ||
| 05 | DeepSeek | DeepSeek V4.1 Flash 1017 | Max | 89.8 | 26m 55s | $0.25 | Compare decks | |||
| Config.11 | DeepSeek | DeepSeek V4.1 Flash 1017 | Max | 89.8Elo 1,878 · 3 decks, 95% interval 77.7–97.6 | 26m 55s | $0.25Reported | Compare decks | Details for DeepSeek V4.1 Flash 1017, MaxElo 1,878 · 3 decks 95% interval: 77.7–97.6 Time: Mean · n=3 Cost: Provider-reported · n=3 Release: Oct 17, 2026 | ||
| 06 | Moonshot AI | Kimi K3.1 Pro | High | 89.6 | 13m 16s | $1.11 | Compare decks | |||
| Config.23 | Moonshot AI | Kimi K3.1 Pro | Low | 73.8Elo 1,680 · 3 decks, 95% interval 48.1–92 | 20m 27s | $1.34Reported | Compare decks | Details for Kimi K3.1 Pro, LowElo 1,680 · 3 decks 95% interval: 48.1–92 Time: Mean · n=3 Cost: Provider-reported · n=3 Release: Oct 23, 2026 | ||
| Config.12 | Moonshot AI | Kimi K3.1 Pro | High | 89.6Elo 1,874 · 3 decks, 95% interval 80.5–97.1 | 13m 16s | $1.11Reported | Compare decks | Details for Kimi K3.1 Pro, HighElo 1,874 · 3 decks 95% interval: 80.5–97.1 Time: Mean · n=3 Cost: Provider-reported · n=3 Release: Oct 23, 2026 | ||
| Config.13 | Moonshot AI | Kimi K3.1 Pro | Max | 87.7Elo 1,841 · 3 decks, 95% interval 71.4–95.2 | 22m 26s | $1.79Reported | Compare decks | Details for Kimi K3.1 Pro, MaxElo 1,841 · 3 decks 95% interval: 71.4–95.2 Time: Mean · n=3 Cost: Provider-reported · n=3 Release: Oct 23, 2026 | ||
| 07 | OpenAI | GPT-6 Sol | Max | 80.1 | 11m 02s | $0.96 | Compare decks | |||
| Config.57 | OpenAI | GPT-6 Sol | Low | 13.9Elo 1,184 · 6 decks, 95% interval 4.2–27.2 | 2m 38s | $0.16API estimate | Compare decks | Details for GPT-6 Sol, LowElo 1,184 · 6 decks 95% interval: 4.2–27.2 Time: Mean · n=6 Cost: API-equivalent estimate · n=6 Release: Sep 22, 2026 | ||
| Config.49 | OpenAI | GPT-6 Sol | Medium | 35.4Elo 1,396 · 5 decks, 95% interval 23.2–48.3 | 3m 48s | $0.33API estimate | Compare decks | Details for GPT-6 Sol, MediumElo 1,396 · 5 decks 95% interval: 23.2–48.3 Time: Mean · n=6 Cost: API-equivalent estimate · n=6 Release: Sep 22, 2026 | ||
| Config.39 | OpenAI | GPT-6 Sol | High | 51.7Elo 1,512 · 5 decks, 95% interval 29.6–71.4 | 5m 34s | $0.58API estimate | Compare decks | Details for GPT-6 Sol, HighElo 1,512 · 5 decks 95% interval: 29.6–71.4 Time: Mean · n=5 Cost: API-equivalent estimate · n=5 Release: Sep 22, 2026 | ||
| Config.31 | OpenAI | GPT-6 Sol | Xhigh | 59.3Elo 1,566 · 4 decks, 95% interval 45.8–73.4 | 21m 18s | $0.87API estimate | Compare decks | Details for GPT-6 Sol, XhighElo 1,566 · 4 decks 95% interval: 45.8–73.4 Time: Mean · n=4 Cost: API-equivalent estimate · n=4 Release: Sep 22, 2026 | ||
| Config.15 | OpenAI | GPT-6 Sol | Max | 80.1Elo 1,741 · 5 decks, 95% interval 65.1–91.7 | 11m 02s | $0.96API estimate | Compare decks | Details for GPT-6 Sol, MaxElo 1,741 · 5 decks 95% interval: 65.1–91.7 Time: Mean · n=5 Cost: API-equivalent estimate · n=4 Release: Sep 22, 2026 | ||
| Config.47 | OpenAI | GPT-6 Sol | Ultra | 40.2Elo 1,431 · 1 deck, 95% interval 11.5–79.6 | 10m 30s | $1.62API estimate | Compare decks | Details for GPT-6 Sol, UltraElo 1,431 · 1 deck 95% interval: 11.5–79.6 Time: Mean · n=1 Cost: API-equivalent estimate · n=1 Release: Sep 22, 2026 | ||
| 08 | OpenAI | GPT-6.1 Sol | Max | 79.3 | 22m 43s | $0.89 | Compare decks | |||
| Config.33 | OpenAI | GPT-6.1 Sol | Low | 58.7Elo 1,561 · 7 decks, 95% interval 43.5–71.6 | 4m 31s | $0.22API estimate | Compare decks | Details for GPT-6.1 Sol, LowElo 1,561 · 7 decks 95% interval: 43.5–71.6 Time: Mean · n=7 Cost: API-equivalent estimate · n=7 Release: Sep 29, 2026 | ||
| Config.26 | OpenAI | GPT-6.1 Sol | Medium | 66.8Elo 1,622 · 5 decks, 95% interval 53.2–80.5 | 6m 37s | $0.38API estimate | Compare decks | Details for GPT-6.1 Sol, MediumElo 1,622 · 5 decks 95% interval: 53.2–80.5 Time: Mean · n=5 Cost: API-equivalent estimate · n=4 Release: Sep 29, 2026 | ||
| Config.40 | OpenAI | GPT-6.1 Sol | High | 50.9Elo 1,507 · 5 decks, 95% interval 38.1–65.4 | 14m 02s | $0.56API estimate | Compare decks | Details for GPT-6.1 Sol, HighElo 1,507 · 5 decks 95% interval: 38.1–65.4 Time: Mean · n=5 Cost: API-equivalent estimate · n=5 Release: Sep 29, 2026 | ||
| Config.34 | OpenAI | GPT-6.1 Sol | Xhigh | 57.9Elo 1,556 · 5 decks, 95% interval 42.2–70.7 | 13m 16s | $0.65API estimate | Compare decks | Details for GPT-6.1 Sol, XhighElo 1,556 · 5 decks 95% interval: 42.2–70.7 Time: Mean · n=6 Cost: API-equivalent estimate · n=6 Release: Sep 29, 2026 | ||
| Config.17 | OpenAI | GPT-6.1 Sol | Max | 79.3Elo 1,733 · 5 decks, 95% interval 70.7–87.4 | 22m 43s | $0.89API estimate | Compare decks | Details for GPT-6.1 Sol, MaxElo 1,733 · 5 decks 95% interval: 70.7–87.4 Time: Mean · n=5 Cost: API-equivalent estimate · n=5 Release: Sep 29, 2026 | ||
| Config.19 | OpenAI | GPT-6.1 Sol | Ultra | 78.3Elo 1,723 · 3 decks, 95% interval 42.5–95.3 | 11m 38s | $0.63API estimate | Compare decks | Details for GPT-6.1 Sol, UltraElo 1,723 · 3 decks 95% interval: 42.5–95.3 Time: Mean · n=3 Cost: API-equivalent estimate · n=3 Release: Sep 29, 2026 | ||
| 09 | Anthropic | Opus 5 | Xhigh | 76.6 | 27m 49s | $10.39 | Compare decks | |||
| Config.20 | Anthropic | Opus 5 | Xhigh | 76.6Elo 1,706 · 2 decks, 95% interval 55.6–90.5 | 27m 49s | $10.39API estimate | Compare decks | Details for Opus 5, XhighElo 1,706 · 2 decks 95% interval: 55.6–90.5 Time: Mean · n=2 Cost: API-equivalent estimate · n=2 Release: Jul 24, 2026 | ||
| Config.36 | Anthropic | Opus 5 | Max | 54.4Elo 1,531 · 3 decks, 95% interval 32.9–74.2 | 38m 12s | $16.45API estimate | Compare decks | Details for Opus 5, MaxElo 1,531 · 3 decks 95% interval: 32.9–74.2 Time: Mean · n=3 Cost: API-equivalent estimate · n=3 Release: Jul 24, 2026 | ||
| 10 | Anthropic | Claude Haiku 5.5 | High | 75.4 | 8m 37s | $0.30 | Compare decks | |||
| Config.54 | Anthropic | Claude Haiku 5.5 | Low | 20.5Elo 1,264 · 3 decks, 95% interval 6.1–40.9 | 4m 30s | $0.13API estimate | Compare decks | Details for Claude Haiku 5.5, LowElo 1,264 · 3 decks 95% interval: 6.1–40.9 Time: Mean · n=3 Cost: API-equivalent estimate · n=3 Release: Oct 7, 2026 | ||
| Config.28 | Anthropic | Claude Haiku 5.5 | Medium | 64.3Elo 1,602 · 6 decks, 95% interval 52–75.4 | 6m 08s | $0.19API estimate | Compare decks | Details for Claude Haiku 5.5, MediumElo 1,602 · 6 decks 95% interval: 52–75.4 Time: Mean · n=6 Cost: API-equivalent estimate · n=6 Release: Oct 7, 2026 | ||
| Config.21 | Anthropic | Claude Haiku 5.5 | High | 75.4Elo 1,695 · 5 decks, 95% interval 55.7–87.5 | 8m 37s | $0.30API estimate | Compare decks | Details for Claude Haiku 5.5, HighElo 1,695 · 5 decks 95% interval: 55.7–87.5 Time: Mean · n=5 Cost: API-equivalent estimate · n=5 Release: Oct 7, 2026 | ||
| Config.42 | Anthropic | Claude Haiku 5.5 | Xhigh | 44.8Elo 1,463 · 3 decks, 95% interval 21.6–67.6 | 15m 12s | $0.33API estimate | Compare decks | Details for Claude Haiku 5.5, XhighElo 1,463 · 3 decks 95% interval: 21.6–67.6 Time: Mean · n=3 Cost: API-equivalent estimate · n=3 Release: Oct 7, 2026 | ||
| Config.29 | Anthropic | Claude Haiku 5.5 | Max | 61.4Elo 1,581 · 3 decks, 95% interval 42.5–77.2 | 46m 22s | $1.04API estimate | Compare decks | Details for Claude Haiku 5.5, MaxElo 1,581 · 3 decks 95% interval: 42.5–77.2 Time: Mean · n=3 Cost: API-equivalent estimate · n=3 Release: Oct 7, 2026 | ||
| 11 | Anthropic | Claude Opus 4.8 | Max | 75.0 | 34m 15s | $11.27 | Compare decks | |||
| Config.27 | Anthropic | Claude Opus 4.8 | Xhigh | 65.1Elo 1,609 · 3 decks, 95% interval 40.5–83.6 | 22m 21s | $5.12API estimate | Compare decks | Details for Claude Opus 4.8, XhighElo 1,609 · 3 decks 95% interval: 40.5–83.6 Time: Mean · n=3 Cost: API-equivalent estimate · n=3 Release: May 28, 2026 | ||
| Config.22 | Anthropic | Claude Opus 4.8 | Max | 75.0Elo 1,691 · 2 decks, 95% interval 60.8–85.8 | 34m 15s | $11.27Reported | Compare decks | Details for Claude Opus 4.8, MaxElo 1,691 · 2 decks 95% interval: 60.8–85.8 Time: Mean · n=2 Cost: Provider-reported · n=2 Release: May 28, 2026 | ||
| 12 | MiniMax | MiniMax M3.1 Flash | Max | 70.7 | 40m 24s | $0.34 | Compare decks | |||
| Config.25 | MiniMax | MiniMax M3.1 Flash | Max | 70.7Elo 1,653 · 1 deck, 95% interval 48.2–89.4 | 40m 24s | $0.34Reported | Compare decks | Details for MiniMax M3.1 Flash, MaxElo 1,653 · 1 deck 95% interval: 48.2–89.4 Time: Mean · n=2 Cost: Provider-reported · n=2 Release: Oct 19, 2026 | ||
| 13 | Anthropic | Claude Fable 5.1 | Max* | 54.8 | 22m 57s | $8.65 | Compare decks | |||
| Config.35 | Anthropic | Claude Fable 5.1 | Max* | 54.8Elo 1,534 · 4 decks, 95% interval 40–68.8 | 22m 57s | $8.65Reported | Compare decks | Details for Claude Fable 5.1, MaxElo 1,534 · 4 decks 95% interval: 40–68.8 Time: Mean · n=1 Cost: Provider-reported · n=1 Release: Sep 1, 2026 | ||
| 14 | Z.AI | GLM 5.3 | Max | 47.2 | 15m 21s | $0.62 | Compare decks | |||
| Config.41 | Z.AI | GLM 5.3 | Max | 47.2Elo 1,481 · 1 deck, 95% interval 14–83 | 15m 21s | $0.62Reported | Compare decks | Details for GLM 5.3, MaxElo 1,481 · 1 deck 95% interval: 14–83 Time: Mean · n=1 Cost: Provider-reported · n=1 Release: Aug 14, 2026 | ||
| 15 | OpenAI | GPT-6 Luna | Max | 44.5 | 25m 40s | $0.09 | Compare decks | |||
| Config.60 | OpenAI | GPT-6 Luna | Low | 6.9Elo 1,048 · 3 decks, 95% interval 1.6–18.1 | 2m 05s | $0.01API estimate | Compare decks | Details for GPT-6 Luna, LowElo 1,048 · 3 decks 95% interval: 1.6–18.1 Time: Mean · n=5 Cost: API-equivalent estimate · n=5 Release: Sep 22, 2026 | ||
| Config.62 | OpenAI | GPT-6 Luna | Medium | 5.6Elo 1,010 · 4 decks, 95% interval 1–17.3 | 1m 50s | $0.02API estimate | Compare decks | Details for GPT-6 Luna, MediumElo 1,010 · 4 decks 95% interval: 1–17.3 Time: Mean · n=4 Cost: API-equivalent estimate · n=4 Release: Sep 22, 2026 | ||
| Config.56 | OpenAI | GPT-6 Luna | High | 14.0Elo 1,185 · 4 decks, 95% interval 4.9–23.7 | 5m 11s | $0.03API estimate | Compare decks | Details for GPT-6 Luna, HighElo 1,185 · 4 decks 95% interval: 4.9–23.7 Time: Mean · n=4 Cost: API-equivalent estimate · n=4 Release: Sep 22, 2026 | ||
| Config.53 | OpenAI | GPT-6 Luna | Xhigh | 25.4Elo 1,312 · 4 decks, 95% interval 14.2–37.8 | 22m 30s | $0.08API estimate | Compare decks | Details for GPT-6 Luna, XhighElo 1,312 · 4 decks 95% interval: 14.2–37.8 Time: Mean · n=5 Cost: API-equivalent estimate · n=5 Release: Sep 22, 2026 | ||
| Config.43 | OpenAI | GPT-6 Luna | Max | 44.5Elo 1,462 · 10 decks, 95% interval 35–54 | 25m 40s | $0.09API estimate | Compare decks | Details for GPT-6 Luna, MaxElo 1,462 · 10 decks 95% interval: 35–54 Time: Mean · n=11 Cost: API-equivalent estimate · n=7 Release: Sep 22, 2026 | ||
| 16 | Xiaomi | MiMo-V2.6-Flash | Max | 43.9 | 73m 31s | $0.20 | Compare decks | |||
| Config.44 | Xiaomi | MiMo-V2.6-Flash | Max | 43.9Elo 1,458 · 2 decks, 95% interval 26–63.7 | 73m 31s | $0.20Reported | Compare decks | Details for MiMo-V2.6-Flash, MaxElo 1,458 · 2 decks 95% interval: 26–63.7 Time: Mean · n=3 Cost: Provider-reported · n=3 Release: Sep 22, 2026 | ||
| 17 | DeepSeek | DeepSeek V4.1 Flash | Max | 42.5 | 16m 45s | $0.14 | Compare decks | |||
| Config.45 | DeepSeek | DeepSeek V4.1 Flash | Max | 42.5Elo 1,447 · 6 decks, 95% interval 30.9–56.5 | 16m 45s | $0.14Reported | Compare decks | Details for DeepSeek V4.1 Flash, MaxElo 1,447 · 6 decks 95% interval: 30.9–56.5 Time: Mean · n=8 Cost: Provider-reported · n=8 Release: Sep 10, 2026 | ||
| 18 | xAI | Grok 4.6 | Max* | 42.2 | 13m 17s | $2.36 | Compare decks | |||
| Config.46 | xAI | Grok 4.6 | Max* | 42.2Elo 1,445 · 5 decks, 95% interval 28.7–58.4 | 13m 17s | $2.36Reported | Compare decks | Details for Grok 4.6, MaxElo 1,445 · 5 decks 95% interval: 28.7–58.4 Time: Mean · n=1 Cost: Provider-reported · n=1 Release: Aug 12, 2026 | ||
| 19 | Z.AI | GLM 5.3 Flash | Max | 37.0 | 27m 42s | $0.24 | Compare decks | |||
| Config.48 | Z.AI | GLM 5.3 Flash | Max | 37.0Elo 1,408 · 3 decks, 95% interval 20.1–54.9 | 27m 42s | $0.24Reported | Compare decks | Details for GLM 5.3 Flash, MaxElo 1,408 · 3 decks 95% interval: 20.1–54.9 Time: Mean · n=3 Cost: Provider-reported · n=3 Release: Aug 26, 2026 | ||
| 20 | OpenAI | GPT-5.6 Terra | Max | 34.5 | 15m 27s | $1.64 | Compare decks | |||
| Config.50 | OpenAI | GPT-5.6 Terra | Max | 34.5Elo 1,389 · 5 decks, 95% interval 19.8–52.9 | 15m 27s | $1.64API estimate | Compare decks | Details for GPT-5.6 Terra, MaxElo 1,389 · 5 decks 95% interval: 19.8–52.9 Time: Mean · n=5 Cost: API-equivalent estimate · n=5 Release: Jul 9, 2026 | ||
| 21 | Qwen / Alibaba | Qwen 3.8 Flash | Max | 31.7 | 30m 08s | $0.19 | Compare decks | |||
| Config.51 | Qwen / Alibaba | Qwen 3.8 Flash | Max | 31.7Elo 1,367 · 3 decks, 95% interval 15.4–52.8 | 30m 08s | $0.19Reported | Compare decks | Details for Qwen 3.8 Flash, MaxElo 1,367 · 3 decks 95% interval: 15.4–52.8 Time: Mean · n=3 Cost: Provider-reported · n=3 Release: Aug 26, 2026 | ||
| 22 | Moonshot AI | Kimi K3 | Max | 27.5 | 13m 38s | $1.73 | Compare decks | |||
| Config.52 | Moonshot AI | Kimi K3 | Max | 27.5Elo 1,331 · 1 deck, 95% interval 5.4–62.9 | 13m 38s | $1.73Reported | Compare decks | Details for Kimi K3, MaxElo 1,331 · 1 deck 95% interval: 5.4–62.9 Time: Mean · n=1 Cost: Provider-reported · n=1 Release: Jul 16, 2026 | ||
| 23 | OpenAI | GPT-5.5 | Xhigh | 18.3 | 11m 29s | $2.56 | Compare decks | |||
| Config.66 | OpenAI | GPT-5.5 | High | 0.9Elo 680 · 3 decks, 95% interval 0.5–1.4 | 7m 28s | $1.76API estimate | Compare decks | Details for GPT-5.5, HighElo 680 · 3 decks 95% interval: 0.5–1.4 Time: Mean · n=3 Cost: API-equivalent estimate · n=3 Release: Apr 23, 2026 | ||
| Config.55 | OpenAI | GPT-5.5 | Xhigh | 18.3Elo 1,240 · 3 decks, 95% interval 8.4–35.1 | 11m 29s | $2.56API estimate | Compare decks | Details for GPT-5.5, XhighElo 1,240 · 3 decks 95% interval: 8.4–35.1 Time: Mean · n=3 Cost: API-equivalent estimate · n=3 Release: Apr 23, 2026 | ||
| 24 | Google | Gemini 3.8 Flash | Max | 13.8 | 16m 18s | $1.93 | Compare decks | |||
| Config.58 | Google | Gemini 3.8 Flash | Max | 13.8Elo 1,182 · 4 decks, 95% interval 5.4–25.9 | 16m 18s | $1.93Reported | Compare decks | Details for Gemini 3.8 Flash, MaxElo 1,182 · 4 decks 95% interval: 5.4–25.9 Time: Mean · n=5 Cost: Provider-reported · n=5 Release: Sep 2, 2026 | ||
| 25 | Meta | Muse Spark 1.3 | Max* | 13.8 | 12m 44s | $1.52 | Compare decks | |||
| Config.59 | Meta | Muse Spark 1.3 | Max* | 13.8Elo 1,182 · 6 decks, 95% interval 6.5–21 | 12m 44s | $1.52Reported | Compare decks | Details for Muse Spark 1.3, MaxElo 1,182 · 6 decks 95% interval: 6.5–21 Time: Mean · n=2 Cost: Provider-reported · n=2 Release: Sep 2, 2026 | ||
| 26 | OpenAI | GPT-5.6 Luna | Xhigh | 4.4 | 11m 59s | $0.12 | Compare decks | |||
| Config.63 | OpenAI | GPT-5.6 Luna | Xhigh | 4.4Elo 967 · 4 decks, 95% interval 1–11.2 | 11m 59s | $0.12API estimate | Compare decks | Details for GPT-5.6 Luna, XhighElo 967 · 4 decks 95% interval: 1–11.2 Time: Mean · n=6 Cost: API-equivalent estimate · n=6 Release: Jul 9, 2026 | ||
| 27 | DeepSeek | DeepSeek V4 Pro 0813 | Max | 4.3 | 27m 15s | $0.46 | Compare decks | |||
| Config.64 | DeepSeek | DeepSeek V4 Pro 0813 | Max | 4.3Elo 963 · 1 deck, 95% interval 1.7–14.9 | 27m 15s | $0.46Reported | Compare decks | Details for DeepSeek V4 Pro 0813, MaxElo 963 · 1 deck 95% interval: 1.7–14.9 Time: Mean · n=1 Cost: Provider-reported · n=1 Release: Aug 13, 2026 | ||
| 28 | Meta | Muse Wonder | Max | 1.7 | 11m 22s | $3.03 | Compare decks | |||
| Config.65 | Meta | Muse Wonder | Max | 1.7Elo 794 · 1 deck, 95% interval 0.3–25.7 | 11m 22s | $3.03Reported | Compare decks | Details for Muse Wonder, MaxElo 794 · 1 deck 95% interval: 0.3–25.7 Time: Mean · n=1 Cost: Provider-reported · n=1 Release: Oct 12, 2026 | ||
| No models match this filter. | ||||||||||
Ranks include all providers. Costs are mean USD per task, using provider-reported charges or API-equivalent estimates. Expand a model for sources, sample counts, and score intervals. Missing values are not ranked.
* Includes decks from runs that were stopped before the model finished; they are being replaced with fresh runs.
03 — Compare decks
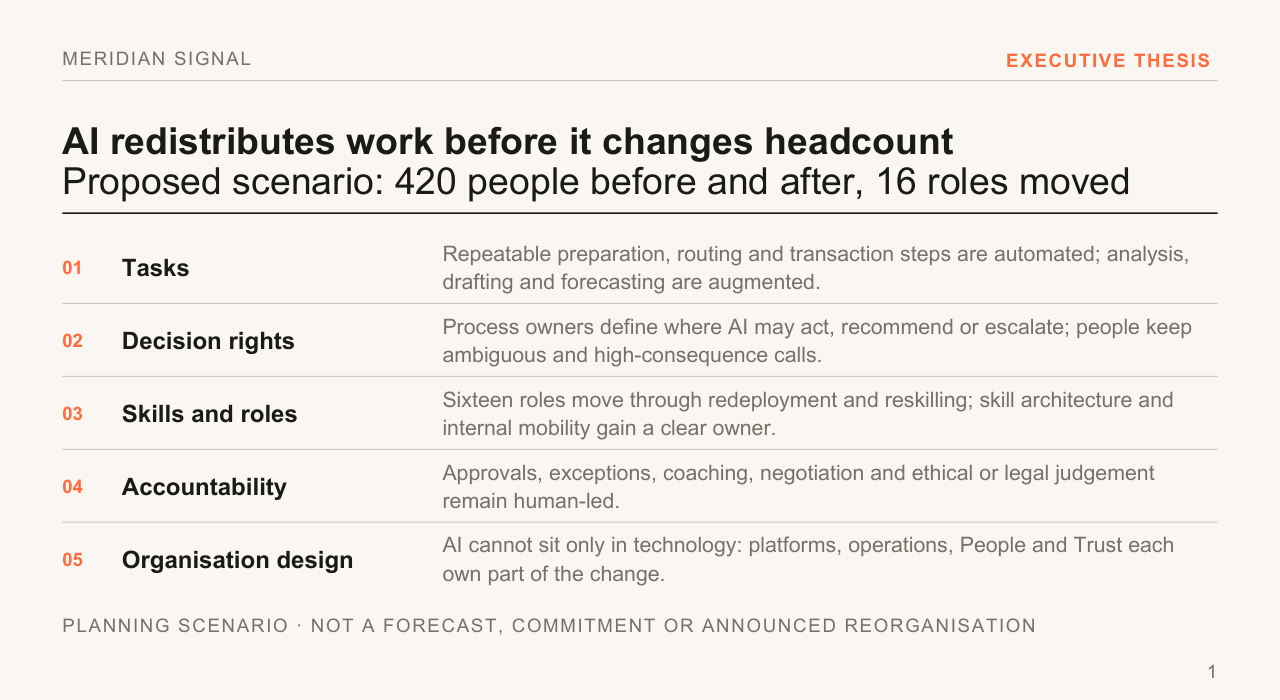
No published render for this configuration; choose another model.
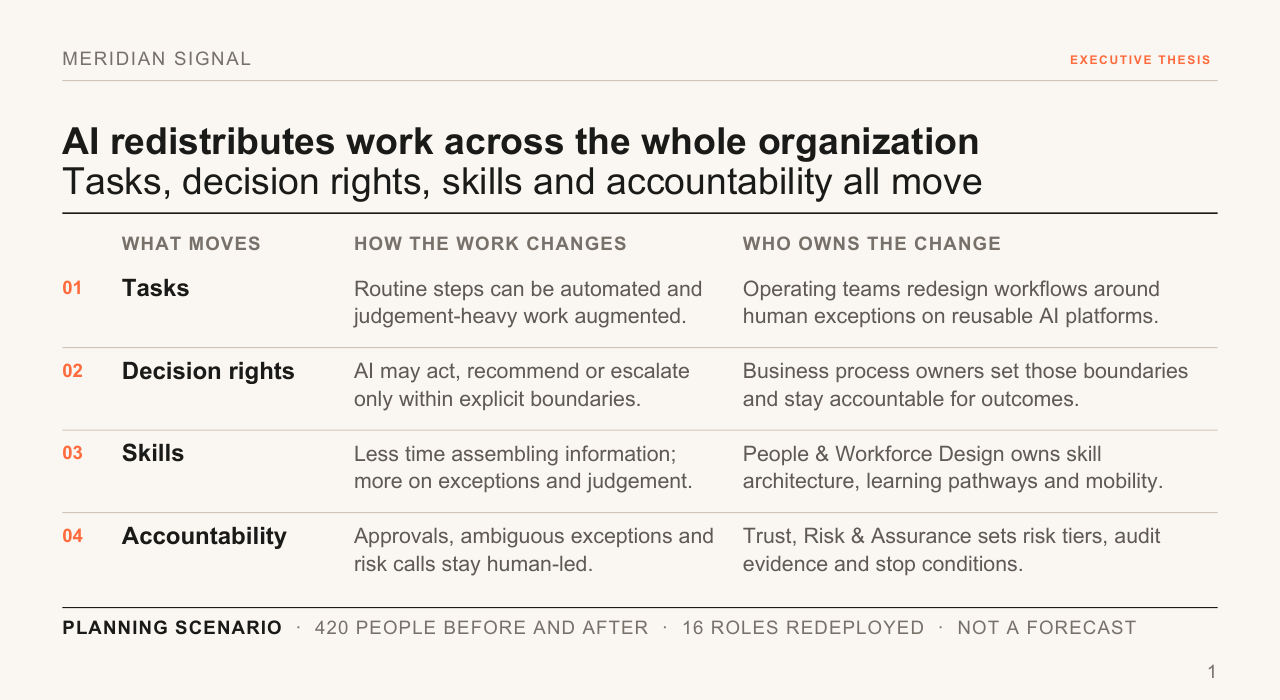
No published render for this configuration; choose another model.
04 — How it works
Stage 01 of 06 · freeze
Every model gets the same golden test case: prompt, source files, requirements, PowerPoint master, and slide library.
GateFrozen before the first run. Every model sees identical inputs.
Stage 02 of 06 · agent run
Each model starts in a fresh agent session and must produce an editable .pptx file.
GateFresh session per run. Nothing carries over between attempts.
Stage 03 of 06 · checks
Automated checks confirm the file is a real, editable deck built on the supplied template.
GateA deck that fails any check never reaches the judges.
Stage 04 of 06 · PowerPoint
Every deck is rendered locally through the same version of Microsoft PowerPoint.
GateOne renderer for every deck, so layout differences come from the model, not the viewer.
Stage 05 of 06 · blind A/B
Claude Opus 5.5 and GPT-6 Sol judge blind A/B pairs of Case 4 decks, shown in both orders. Human A/B reviews and feedback check that the panel agrees with people.
GateJudges never see model names, and each pair is shown in both orders to cancel position bias.
Stage 06 of 06 · Bradley–Terry
I fit the pairwise judgments into a win score and Elo equivalent, alongside sample size, time, cost, and rendered evidence.
GateRatings are refit whenever new decks join the pool.
Reading the score
The win score is the estimated chance of beating a typical rated configuration in a blind comparison. The Elo rating shows the same result on a chess-style scale.
Try it: compare any two configurations
98%Claude Opus 5.5 / XHigh is expected to win 98% of blind comparisons against GPT-6.1 Sol / High.
Their 95% intervals do not overlap, so this is a real difference in this deck pool.
Two blinded AI judges, Claude Opus 5.5 and GPT-6 Sol, compare Test Case 4 decks. Their wins and ties are fitted with a Bradley–Terry model, which gives every configuration one strength rating. The 0–100 win score is that rating's chance of beating a typical configuration; Elo shows the same rating with 1500 as average. Ratings can shift when new decks join the comparison pool.
Human A/B reviews test agreement with the panel; they do not change its ratings. Models with few decks or overlapping confidence intervals may be too close to distinguish reliably.
Marked results still include some of the 33 decks from runs that an earlier version of the benchmark stopped before the model could finish reviewing its work. They stay in the ratings until fresh, uninterrupted runs of the same model and effort replace them: Claude Fable 5.1 / Max (3), Grok 4.6 / Max (4), Muse Spark 1.3 / Max (4).
Current release: local-v38 · benchmark version 0.38.0.
PowerPoint master
Reusable layout definitions from the supplied corporate system.
Slide template
Example slides from the companion design library.
Human spot-checks are called out in the published results.